---
title: Call quality metrics
description: "What the three scores on a call's page measure: Call Quality, AI Relevancy and Faithfulness, and when one of them has no score."
---
Voice agents
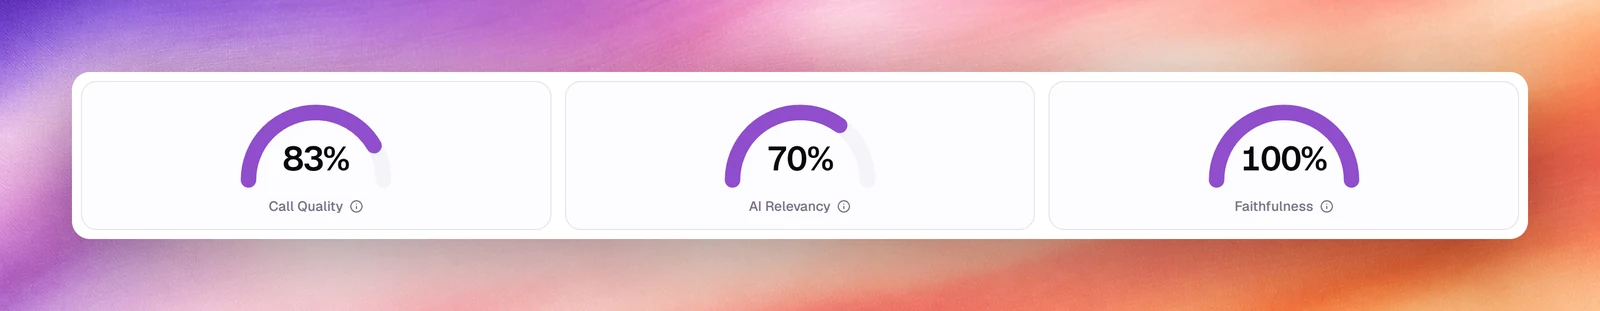
Every finished call is scored after it ends and the results sit at the top of
[Call details](/operate/call-details) as three gauges. The scores are produced by a
model that reads the transcript; they are an opinion about the conversation, not a
measurement of the audio.
## Call Quality
A holistic score from 0 to 100 evaluating the overall conversation flow, coherence,
naturalness and task completion. The **Quality assessment** card on the same page is
the written explanation of this number: it names what scored well (staying on task,
clear steps, a polite tone) and what pulled the score down (an awkward repeat, a
robotic phrase).
Use it to rank calls for review. A prompt change that lifts the typical Call Quality
across a week of calls is a change worth keeping.
Call Quality has no formula. It is one judgement about the whole call, so read it
as a ranking, not as a measurement: a 71 and a 74 are the same call twice.
## AI Relevancy
Every reply the agent made is scored on its own, from 0 to 1, for how well it
addressed what the caller had just said. The gauge is the mean of those scores:
$$
\text{AI Relevancy} = \frac{1}{n}\sum_{i=1}^{n} r_i
\qquad r_i \in [0, 1]
$$
where $n$ is the number of agent turns. Two consequences are worth knowing before
you read the number.
**A mean hides where the failure was.** Twelve turns at 1.0 with one at 0 scores
92%. So does twelve turns at 0.92. The first is one broken answer worth fixing; the
second is an agent that is slightly off the whole way through, which is a prompt
problem. The gauge cannot tell you which, so open the transcript.
**Short calls swing hard.** One irrelevant reply costs $100/n$ points, so on a
4-turn call it costs 25 and on a 40-turn call it costs 2.5. Comparing the relevancy
of a 30-second call against a 5-minute one compares almost nothing; compare medians
across many calls of similar length instead.
A low relevancy next to a high Call Quality is the common shape, and it means the
agent was polite and fluent but did not answer the question. Check the **Tasks** in
the prompt and whether the agent had the tool or the knowledge it needed.
## Faithfulness
Whether what the agent said is supported by what it actually retrieved. It is a
proportion of the agent's checkable statements, so it lands between 0 and 1 and the
gauge shows it as a percentage:
$$
\text{Faithfulness} = \frac{\text{statements supported by the retrieved text}}{\text{statements the agent made that can be checked}}
$$
75% means one claim in four had no support in the documents that came back. That is
the definition of the metric; the platform does not publish how it splits an answer
into statements, so treat a difference of a few points as noise and a difference of
tens as real.
Two things it does not measure. It does not check whether your documents are right,
only whether the agent stayed inside them, so an agent quoting an out-of-date price
faithfully scores 100%. And it says nothing about the retrieval itself: if the search
returned the wrong page and the agent summarised that page correctly, faithfulness is
perfect and the answer is still wrong.
When the call used no knowledge base the gauge shows a dash instead of a
percentage, and its info icon reads **Knowledge base not used**, because the
denominator is zero. An agent without a [Knowledge Base tool](/build/tools/knowledge-base) never
has a faithfulness score, and neither does a call where the agent simply never
searched.
A low score means the agent said something the retrieved documents do not support.
Read the **Used search_knowledge_base** rows in the transcript to see what came back,
then tighten the prompt's guardrails or the documents themselves.
## Reading the three together
The scores answer different questions, and the useful information is usually in
where they disagree.
| Call Quality | AI Relevancy | Faithfulness | What it usually means |
| --- | --- | --- | --- |
| High | High | High | Nothing to do. |
| High | Low | any | Fluent and polite, but not answering. A prompt problem. |
| Low | High | any | Right answers delivered badly: repeats, dead air, an abrupt end. |
| any | any | Low | The agent went beyond its documents. Guardrails, or the documents. |
| any | any | No score | No knowledge base was searched. Not a failure. |
## Where the scores appear
- The gauges on each call's page, with the written explanation of **Call Quality**
in the **Quality assessment** card when the scoring produced one.
- **Overall Success Rate** and the **Success Rate** tabs on the
[Dashboard](/operate/dashboard) summarise task completion, not these scores.
- The scores are not offered as columns in Call Logs.
## Related
- [Call details](/operate/call-details)
- [Evaluations](/test-and-improve/evaluations)
- [Knowledge base tool](/build/tools/knowledge-base)
- [Prompting guide](/build/prompting/prompting-guide)